What Is Jev? Fast AI Decisions Without Generating Text
See how Jev AI turns state into typed decisions for routing and classification, with API examples, pricing, limits, and guidance on when to use it.

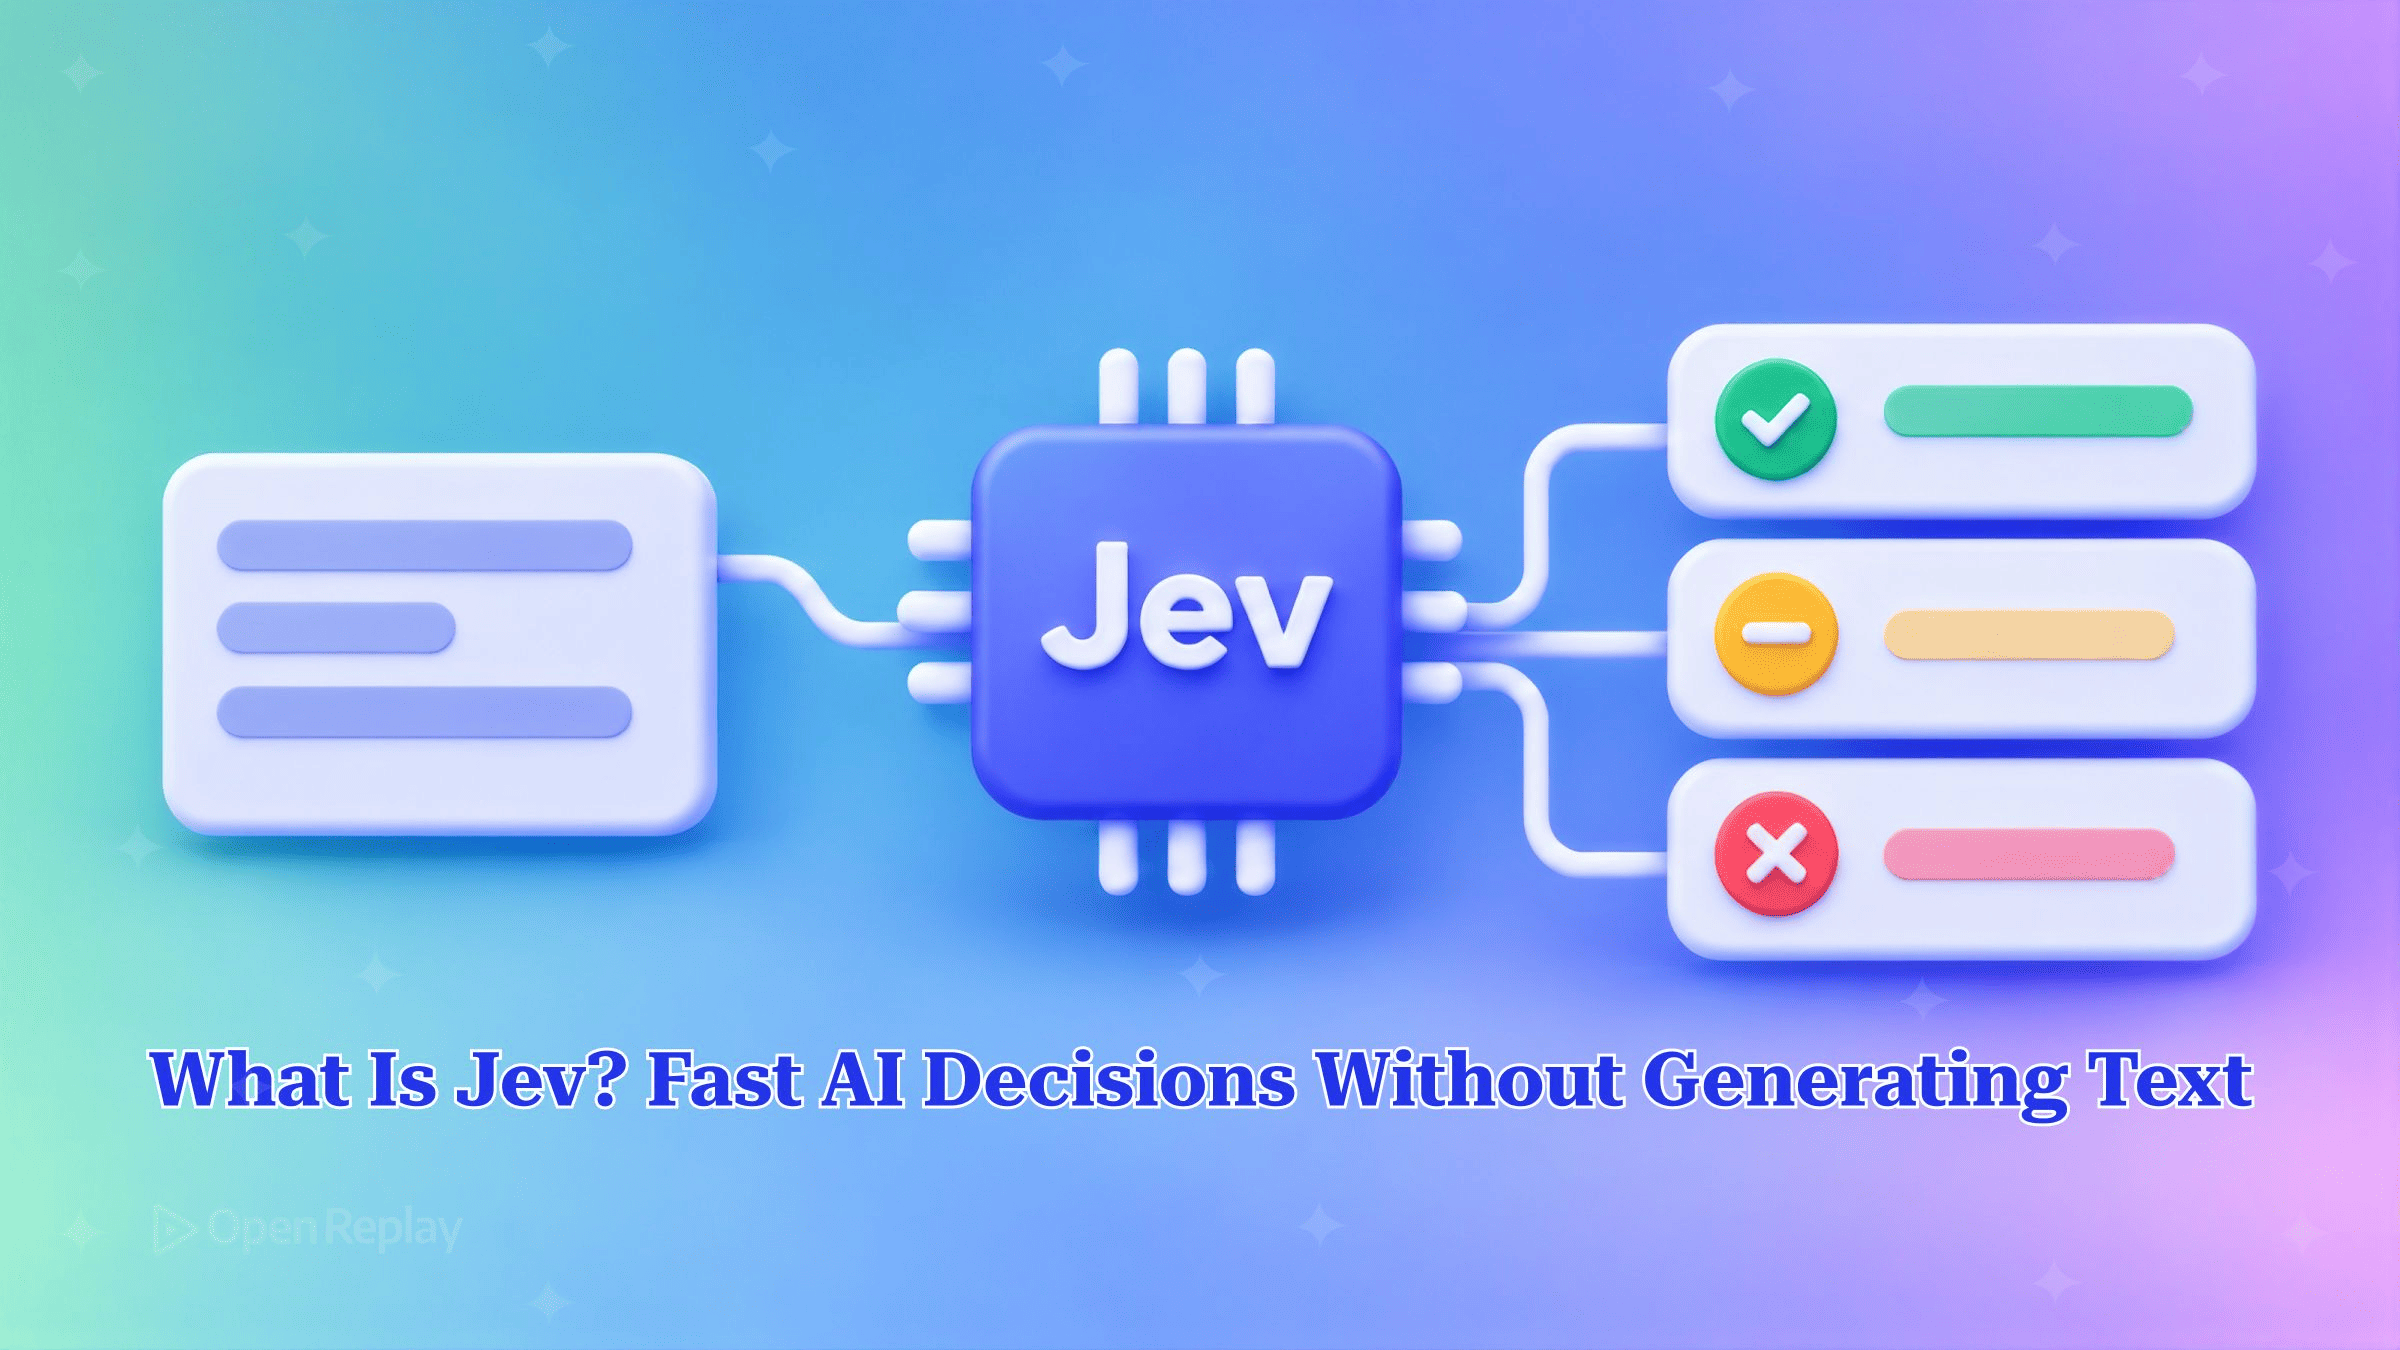
Jev is a decision model from TypeSafe AI. You send it a piece of state and a set of typed questions, and it sends back a structured answer with probabilities for each question. It does not generate text.
If your routing step is a chat completion that asks for JSON and then runs json.loads inside a try block, you already know the costs: you wait on generated tokens, you pay for them, and now and then the output fails your schema. This article covers what Jev returns, what a request looks like against TypeSafe’s own endpoint, and which of your LLM decision steps it can realistically take over.
Key Takeaways
- Jev is the first of TypeSafe AI’s System One models. It was released on 15 September 2026 and answers typed questions with structured values, not prose.
- A Jev request has three required top-level fields,
state,modelandquestions. The response holds ananswersobject keyed by your question ids, plus tokenusage. - Jev has three question types for text decisions. Choice picks one option from up to 255, Score places input on an ordered rubric of 2 to 10 levels, and Noul returns the probability that a yes/no answer is yes.
- TypeSafe prices Jev at $0.042 per million input tokens, and output tokens are free.
- Jev’s answers always come from the answer space defined in the request. That rules out parsing and schema errors, but it does not make the answers correct.
What Is Jev AI?
Jev is a TypeSafe AI model that makes decisions where a normal LLM would write text, and it is the first model in a class TypeSafe calls System One models. In its launch announcement, TypeSafe described it as a new class of frontier models built to make fast, structured decisions that software can use directly. The name borrows Kahneman’s fast, intuitive “System 1” mode of thinking. Access is through early access.
How Does Jev Turn State Into Typed Answers?
Jev takes a state (text or JSON), a model identifier and a map of questions, and returns one typed answer per question, each with probabilities. It evaluates all the questions in parallel. The Noul documentation notes that adding questions to a request barely changes response time. You choose the question ids yourself, and they are not sent to the model.
The API reference defines three question types for text decisions. A fourth type, box, locates a region in an image and is only available behind an opt-in experimental header.
| Type | Use when | Inputs | Returned fields |
|---|---|---|---|
| Choice | The answer is one of several options | instructions, plus criteria mapping each option (up to 255) to a description or null | choice, probabilities, confidence |
| Score | The answer is a degree on an ordered scale | instructions, plus criteria as an ordered array of 2 to 10 levels | score, legend (level index to label), probabilities, confidence |
| Noul | The answer is yes or no | instructions, optional criteria with true/false descriptions | noul (probability 0 to 1) |
A Noul answer is one number between 0 and 1 and has no separate confidence value. With only two outcomes, a single probability fully describes both of them.
A Noul Request and Response
The request below asks two yes/no questions about a single support message. It is sent to POST https://api.typesafe.ai/v1/systemone with a bearer token. Requests use the jev-latest alias, and the response reports which concrete version served the call. The models page lists the version the alias currently resolves to.
curl -X POST https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-latest",
    "state": "My order arrived damaged and I want my money back.",
    "questions": {
      "wants_refund": {
        "type": "noul",
        "instructions": "Is the customer asking for a refund?"
      },
      "mentions_damage": {
        "type": "noul",
        "instructions": "Does the customer report a damaged item?",
        "criteria": {
          "true": "Describes the product as broken, damaged, or defective",
          "false": "No mention of physical damage"
        }
      }
    }
  }'
The response follows the shape below. The probabilities and token counts are illustrative, not recorded output. The recorded examples in TypeSafe’s Noul docs are jev-1.13.0 outputs.
{
  "model": "jev-1.14.0",
  "answers": {
    "wants_refund": { "type": "noul", "noul": 0.97 },
    "mentions_damage": { "type": "noul", "noul": 0.95 }
  },
  "usage": { "input_tokens": 120, "output_tokens": 2 }
}
output_tokens still shows up in usage even though output is not billed. Any HTTP client can send this body. TypeSafe also ships a Python SDK (pip install typesafe-sdk, imported as typesafe_sdk, called through client.system_one) according to the quickstart, and a JavaScript/TypeScript SDK published as @typesafe-ai/sdk.
When Should You Use Jev for Routing, Classification and Tool Selection?
Jev fits decision steps that have a finite answer space: routing a request, classifying a ticket, scoring content against a rubric, or picking a tool for an agent. If your code already parses a label or a number out of a chat completion, that step is a candidate.
Sending a support message to a team is a Choice question, because the answer is exactly one of several options:
from typesafe_sdk import Choice, TypeSafeClient

TEAMS = {
    "billing": "Charges, invoices, refunds, payment methods",
    "technical": "Bugs, errors, outages, integration problems",
    "account": "Login, password resets, access, account settings",
}

def route_ticket(message: str) -> str:
    # TypeSafeClient reads TYPESAFE_API_KEY from the environment.
    with TypeSafeClient(model="jev-latest") as client:
        response = client.system_one(
            state=message,
            questions={
                "team": Choice(
                    instructions="Which team should handle this support message?",
                    criteria=TEAMS,
                ),
            },
        )
    answer = response.answers["team"]
    if answer.confidence < 0.8:
        return "triage"
    return answer.choice
The function returns one of the three dictionary keys or falls back to "triage", so there is no string to validate. The 0.8 cutoff is a placeholder for you to tune against your own traffic, not a TypeSafe recommendation. For Noul questions, TypeSafe’s docs suggest 0.7 and 0.3 as starting thresholds, with the band in between sent to human review.
Routing is also where Jev pairs with a model gateway such as 9router: the gateway sends requests to models, while Jev makes the routing decision.
What Can’t Jev Do?
Jev does not generate free-form text. A pipeline that uses it to route or classify a message still needs a generative model to write the reply. The launch post presents giving up text generation as a deliberate trade for speed and cost. In practice that means Jev picks the team, the tool or the priority, and an LLM still writes the email, the summary or the code.
What Are Jev’s Limits and Caveats?
Jev is a proprietary model served from TypeSafe’s hosted API. TypeSafe has not published weights. The only levers you have are the instructions and criteria you write. The service is in early access, so expect the API surface, model versions and pricing to change. The launch post itself says pricing may move.
TypeSafe prices Jev at $0.042 per million input tokens with output free, and quotes 70 to 500 milliseconds per call. The 193.6x faster, 444.6x cheaper headline figures come from TypeSafe’s own workflow evaluations. Those evals score models against the averaged answers of two large reference LLMs, and TypeSafe describes the gains as the high end of what to expect in practice. On the same benchmark Jev scores about 68%, which places it with mid-tier LLMs. That figure measures agreement with reference models, not accuracy against human-labelled ground truth. Independent tests have come out lower on some tasks. In a public 2,000-email phishing benchmark, Jev scored 62.6% on a single “is this phishing?” question, against 81.3% for Claude Haiku 4.5. Benchmark your own task before you swap anything out.
Type-safe does not mean correct. The answer space constrains the output, which removes schema failures, but Jev can still pick the wrong option with high confidence. Treat its probabilities as signals to threshold, log and review.
Conclusion
Jev turns a decision step into a typed function call: state and questions go in, probabilities come out, and nothing needs parsing. It does not replace your generative model. It replaces the LLM calls whose only job is to output a label. A good next step is to take one existing classification or routing prompt, rewrite it as a Choice or Noul question, and run both versions on the same sample of real traffic before you trust either.
FAQs
Should I use a Noul or a Score for questions about degree, like skill level or urgency?
Use a Score. A Noul returns only the probability that the answer is yes, so 0.5 means the model is split, not that something sits at a medium level. TypeSafe's docs show this with the question 'Is the candidate strong in Python?' Four resumes returned Noul values of 0.03, 0.14, 0.81 and 0.92. A four-level Score placed the same resumes at 0.0, 1.0, 2.05 and 2.89, each on or near a level the developer defined.
How do I handle a decision with more than 255 options in a Choice question?
Split it into two stages. A single Choice accepts up to 255 options. For larger sets, TypeSafe's launch post describes scoring candidates independently first, then running an explicit Choice over the top few. TypeSafe says this is slower than a single call. Option descriptions are part of the request, so they also count against the 64k-token per-request context limit.
Does Jev work with the Vercel AI SDK?
Yes. Vercel ships the @ai-sdk/typesafe-ai provider, and Vercel AI Gateway lists Jev under the model id typesafe-ai/jev. Calls go through an experimental AI SDK 7 function, so its name and shape may still change. The provider renames Noul to 'boolean' and returns the answer in a probability field instead of noul, so a question copied from TypeSafe's docs needs its type changed from 'noul' to 'boolean'. Choice and Score keep their names.
How much input can a single Jev request contain?
By default, a Jev request has to fit two limits: 64k tokens for the state plus all questions, and 32k tokens for the state plus any one question. There is no separate cap on how many questions you send. Sending the TypeSafe-Danger-Zone-Long-Context header set to true raises both limits to 262k tokens on Jev 1.13 and 1.14. TypeSafe says long context is slower and less accurate than the default limits, so turn it on only for requests that need it.
Gain Debugging Superpowers
Unleash the power of session replay to reproduce bugs, track slowdowns and uncover frustrations in your app. Get complete visibility into your frontend with OpenReplay — the most advanced open-source session replay tool for developers.
Star on GitHub12k